Adrien Oliva Bioinformatics · Production Systems
CVConsulting
Menu
Close Expertise What I build Pricing Case studies
Send enquiry →

Bioinformatics consulting for labs, biotechs and research institutes.

  • Microbiome & pathogen ↓ Nanopore sample–to–report, cut from weeks to two days.
  • NGS & targeted genomics ↓ Targeted panels, pharmacogenomics, COVID/TB surveillance and variant workflows.
  • Population genomics & arrays ↓ Cohort-scale association testing with VariantSpark.
  • Data platforms & governance ↓ GeneGuardian: dynamic consent live at a pilot hospital, on FHIR and GA4GH.

I build NGS, microbiome and targeted genomics pipelines inside your own cloud, validated and documented, then hand them to the people who will run them. They keep running after I leave. No black box, no lock-in, no platform to rent.

Send an enquiry ↗ See how an engagement runs → Read the case studies ↓

Biotechs · Research institutes · Core facilities · Diagnostic labs · AU · EU · Remote

Clients & partners in
8 countries
Peer-reviewed
6 Q1
Sequencing
NGS · 16S · targeted
Compliance
HIPAA · GDPR · GA4GH
Based
Full remote · Australia (QLD / SA) · Europe · Switzerland

Expertise

Four kinds of data. One way of working.

The assay changes from project to project. What doesn't change is the destination: a pipeline running in your own infrastructure, with the documents that let you defend it.

Microbiome & pathogen

Community profiling, pathogen detection and surveillance, from raw reads to a report a non-specialist can act on.

Full-length 16S & ITS on Nanopore MinION
EPI2ME wf-16s · SILVA · OTU & ASV · PICRUSt2
Illumina comparison · outbreak & surveillance panels

Case studiesMicrobiome & pathogen →
NGS & targeted genomics

Short-read NGS and targeted workflows through to interpretation: QC, alignment, variant calling, annotation, drug-response calling, and reporting.

Illumina WGS · tiled amplicon (SARS-CoV-2, TB)
BWA · Bowtie2 · minimap2 · GATK · DeepVariant
PharmCAT · PharmGKB · sVEP · reporting

Case studiesPharmacogenomics at scale →NGS & WGS →

Population genomics & arrays

Cohort-scale questions: association testing, population structure, and the reference-bias problems that quietly distort results in under-studied groups.

SNP arrays · genotyping pipelines
GWAS · PLINK · ADMIXTURE · ADMIXTOOLS
vg · minigraph pangenomes · reference bias · ancient DNA

Case studiesPangenome →NGS & WGS →

Data platforms & governance

The layer that decides whether the data can be shared at all: federated discovery, consent, and sovereignty across institutions and borders.

GA4GH · beacons · sBeacon
FHIR · dynamic consent
GDPR · HIPAA · cross-border access

Case studiesGeneGuardian →sBeacon deployments →

See the relevant track record →

Built and deployed with

  • CSIRO
  • Mayo Clinic
  • CNRS
  • Univ. Paris-Saclay
  • Partners in Indonesia & Korea

What I build

Two ways to start.

Each one is scoped, fixed-price and ends with something your team owns and can run without me. Most clients begin with the diagnostic because it is the cheapest way to find out whether the rest is worth doing.

Start here · 1 week

Diagnostic

A week inside your data and infrastructure, ending in a written assessment you could hand to a board or a grant reviewer.

  • Pipeline, cost and bottleneck audit
  • Reproducibility and compliance gaps
  • Costed roadmap with options

Fixed fee Credited in full against a sprint or pilot started within 60 days

2–6 weeks · fixed price

Pipeline & Cloud Sprint

Build, harden or migrate a genomics pipeline on AWS or HPC — Nextflow or Snakemake, with the validation documents that let you defend it.

  • NGS, targeted panels and variant reporting
  • Pharmacogenomics (PharmCAT)
  • Pathogen surveillance
  • Validation report, SOP, cost monitoring, handover

Fixed price per sprint 2, 4 or 6 weeks

Training

I build it. Then I teach it.

A pipeline nobody understands is a pipeline you are renting from whoever wrote it. Every engagement ends with your people able to run the thing. These three can also be booked on their own, without a build.

Hands-on · your data

Training

Sessions with the people who will actually run the pipeline: how it works, how it fails, and what to do at 6pm when it fails. On your data and in your environment, never on a toy dataset.

One session · whole group

Seminars

A talk for the wider team on what a sequencing pipeline in production actually demands: reproducibility, validation, provenance and cost. Pitched at scientists rather than engineers.

One or two days

Workshops

Guided exercises on Nextflow, containers and version control, using a public dataset or your own. People leave with a workflow they wrote and can rerun.

Where I help

If one of these is familiar, we should talk.

These are the situations I get called about. The underlying assay changes — microbiome one month, pharmacogenomics the next — but the problem underneath is usually one of these six.

“Only one person can run our pipeline.”

It works, but it lives in someone's head and their home directory. When they take leave, or leave, the lab stops.

NextflowSnakemakecontainersSOPsteam training

“We can't reproduce last year's analysis.”

Versions drifted, parameters weren't recorded, the reference changed. A reviewer or an auditor asks, and the answer takes three weeks to reconstruct.

provenanceversioningvalidation reportQC gates

“Samples are queuing and we can't hire.”

The backlog grows faster than recruitment. A fixed-price sprint absorbs it and leaves you faster than you were before.

Targeted NGS16SNanoporeSNP arrays

“Nobody can explain the cloud bill.”

Compute costs climb and no one can attribute them to a run, a project or a customer. Usually fixable in days, not months.

AWSHPCcost attributionright-sizingspot

“Someone rebuilds this report every week.”

A manual assembly step — reports, curation triage, literature and metadata wrangling — eating a scientist's day. Automated with a human still in the loop, and measured against what you do now.

report generationcuration triageLLM layer

“We can't share the data we're funded to share.”

Consent, sovereignty and cross-border rules block a collaboration. I have built the consent and federation layer for exactly this, in a pilot hospital, research labs (Indonesia, Korea) and university settings.

GA4GHFHIRbeaconsGDPR · HIPAAdynamic consent

Pricing

Fixed price, agreed before I start.

Every engagement is quoted as a fixed price, in writing, before any work begins. What moves that price is scope: how many assays, which platform it has to run on, how much of your infrastructure I touch, and how much validation evidence you need at the end. If the budget doesn't fit, I cut scope rather than quality — you get fewer segments, not a worse pipeline.

Every engagement runs the same way regardless of size: a free intro call, a one-week diagnostic whose fee is credited in full if you continue within 60 days, then the build itself in scoped, reviewed segments. See how it runs →

Fixed price, quoted in writing 50% on signature, 50% on delivery Scope cut before price You own the code and the documentation Invoiced in your currency

How an engagement runs

You always know what the next decision costs.

Work is cut into segments with a review at the end of each one. You approve the next segment or you stop — and if you stop, you keep everything built so far, running, in your own account.

01 · Free

Intro call

Thirty minutes. Your data, your platform, the question you actually need answered. If I'm not the right person I say so and point you at who is.

Out: go / no-go

02 · Fixed fee

Diagnostic

One week inside the real thing. I read the code, the infrastructure and the constraints, and cost the options.

Out: written assessment + costed roadmap

03 · Fixed price

Build, in segments

Each segment is scoped, priced and shipped into your environment. Built in your cloud from day one, never on my laptop.

Out: working code, in your account

04 · Your call

Review & decide

Demo, review period, then one decision: continue to the next segment, revise this one, or close out.

Out: next segment, revision, or handover

05 · Included

Handover

Validation report, SOPs, cost monitoring and a walkthrough with the people who will run it. Then I leave.

Out: your team owns it

The loop Steps 03 and 04 repeat for as long as they're worth repeating. The diagnostic fee comes off the first build segment, so starting small costs you nothing if you continue — and the diagnostic is all you have spent if you don't.

Case studies

Worked examples across the sequencing problems clients bring.

Microbiome, targeted NGS, precision medicine and pharmacogenomics are different problems. Each example shows the same operating principle: a defensible workflow, clear limits, reproducible outputs and a handover path.

Click any card to open the full write-up: the method, the numbers and what I would not claim.

Commercial genomics · 2026

Production

Microbiome and pathogen sample-to-report

Architected and deployed a full Oxford Nanopore 16S analytical stack: live DNA sample through to microbiome and pathogen detection report. Built the SQL layer, automated reporting and SOPs needed for reproducible commercial delivery.

Weeks → 2 days Nanopore · 16S · pathogen reporting

Read the microbiome case study →Workflow, QA, reporting and handover

CSIRO + Mayo Clinic · 2025

NGS case study

Sequencing data into defensible precision medicine

Led a multi-institution precision medicine project with Mayo Clinic and Université Paris-Saclay, using short-read sequencing data to quantify reference-bias effects on variant calls, PCA, D and F-statistics, and improve analyses for underrepresented populations.

4 led · 3 institutions NGS · pangenome graphs · HPC

Read the precision medicine case study →Sequencing data, reference bias and outputs

CSIRO · 2022–2025

Deployed

Targeted genomics into partner AWS accounts

PharmCAT, sVEP, VariantSpark and sBeacon deployed inside partner AWS accounts in Indonesia and Korea, supporting pharmacogenomics, infectious-disease surveillance and data sovereignty. Staff trained to run and maintain each stack.

2 countries · 4 stacks Pharmacogenomics · variant calling · training

Read the PGx case study →Transparent code and method walkthrough

University of Adelaide · CSIRO · Genics

NGS · WGS · 16S

The sequencing data itself, across platforms

Illumina whole genomes (ancient, human, rat, viral), tiled-amplicon SARS-CoV-2 and TB, and full-length Nanopore 16S. Benchmarked 30 mapping strategies for reference bias, built pangenome graphs, and ran variant calling, PharmCAT and lineage assignment from raw FASTQ.

30 mappers benchmarked Illumina · Nanopore · SNP arrays

Read the NGS & WGS case study →Projects, toolchain and limits

CSIRO / AEHRC · 2024

In customer hands

GeneGuardian — AI-assisted data governance

Co-led a dynamic consent platform for genomic data: FHIR integration, storage and cloud decisions, and researched and developed blockchain and decentralised-storage layers, designed to GA4GH standards. Live at a pilot hospital. Published a Q1 review on genomic data governance alongside it.

Dynamic consent, live at a pilot hospital FHIR · GA4GH · GDPR

Read the GeneGuardian case study →Design decisions, limits and sources

Peer-reviewed

6 Q1 papers

The methods are public and checkable

Six Q1 papers across computational biology, population genomics and genomic data governance. If you want to audit how I work before you hire me, you can read it.

Publications & talks → Google Scholar · ORCID

Who you get

One person. The same one throughout.

No account manager, no handover to a junior after the contract is signed. The person who scopes your project is the person who writes the code and trains your team.

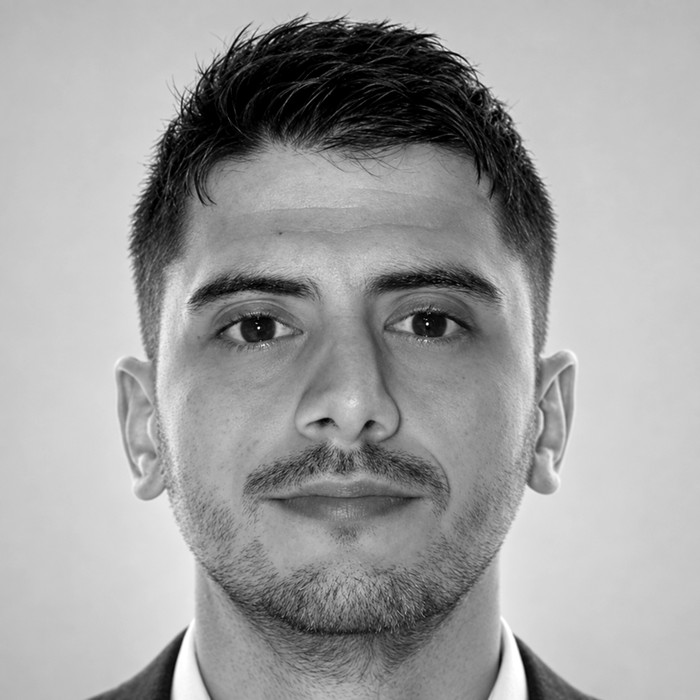
Adrien Oliva

Adrien Oliva

PhD computational biologist · Full remote · English & Français

I spent three years at CSIRO putting genomics workflows into partner AWS accounts in Indonesia and Korea, including pharmacogenomics, COVID-19/TB surveillance and population genomics. That is where I learned that the hard part is never the algorithm. It is the validation document, the cost alert nobody set up, and the person on leave who was the only one who could restart the run.

Six Q1 papers across computational biology, population genomics and genomic data governance. Much of it has already been defended in peer review.

Day to day, I also build with LLMs and agent frameworks — Claude, GPT and local models — to speed up exactly this kind of work. Not a packaged service on this site yet, but ask if it is relevant to your project.

Full CV and publications →

Contact

Bring the problem. Leave with a plan.

The platform, the number of samples and the question you want answered are enough to start. I reply within 48 hours.

Book a 30-minute call

No pitch deck. You describe the problem, I tell you whether it's worth doing, what it would cost, and whether I'm the right person for it.

Email me ↗
Email
contact@adrien-oliva.com
Working hours
Full remote, across Australian and European time zones.
Confidentiality
NDA signed before any data or code changes hands. No client data leaves your environment.
Languages
English · Français

Used only to answer your enquiry and take pre-contractual steps. Please don't include patient-identifiable data or credentials in this form. See the privacy policy.

© 2026 Adrien Oliva · Full remote · Australia (QLD / SA) · Europe · Switzerland

Expertise What I build Where I help Pricing Training How it runs Who you get Case studies CV Privacy Contact

Independent consultant, sole trader · ABN 80 870 990 323. Insurance details can be provided once engagement terms are confirmed. Work is delivered into the client's own infrastructure; clients retain ownership of all code and documentation produced under engagement.

×

Send an enquiry

A couple of lines about the platform and the question is enough. I reply within 48 hours.

Please don't include patient-identifiable data or credentials. See the privacy policy.